What RECAST Does 1× speed
RECAST Pipeline
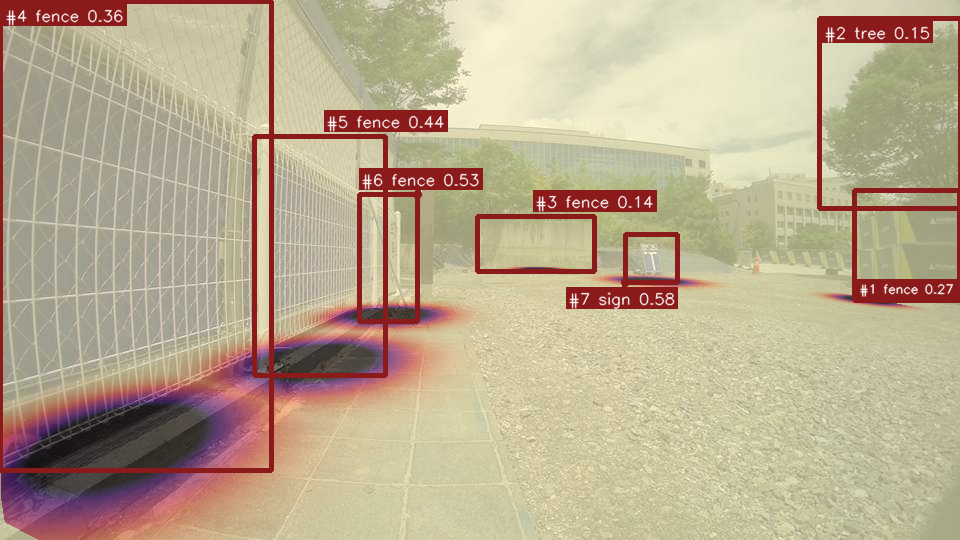
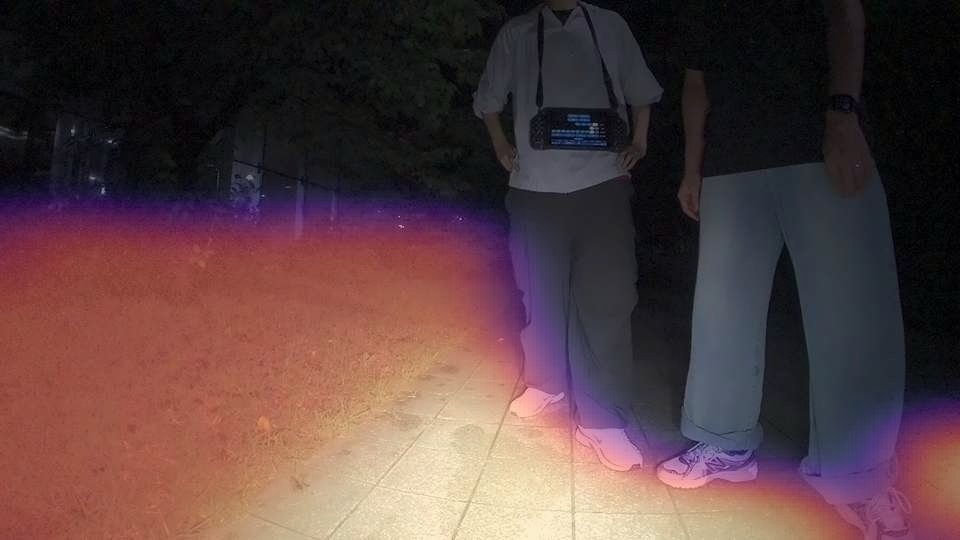
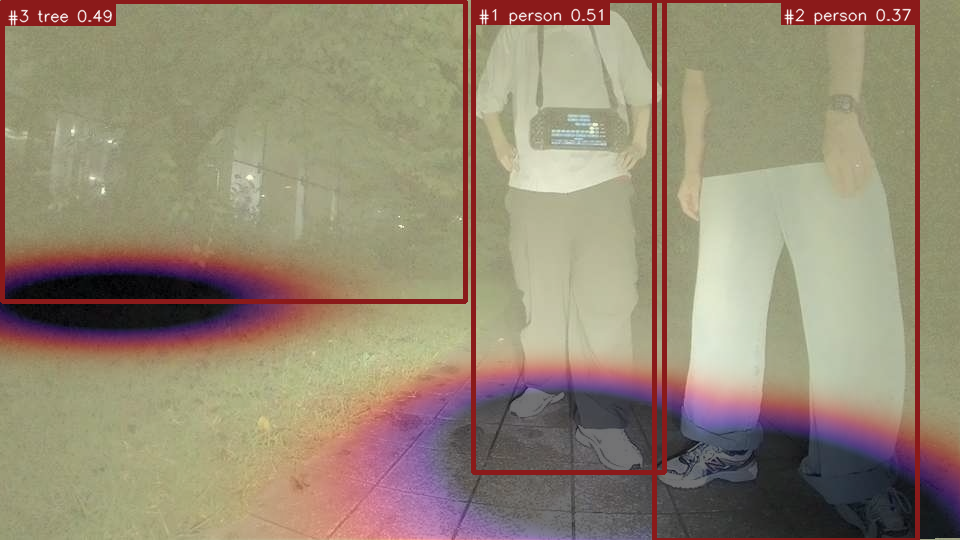
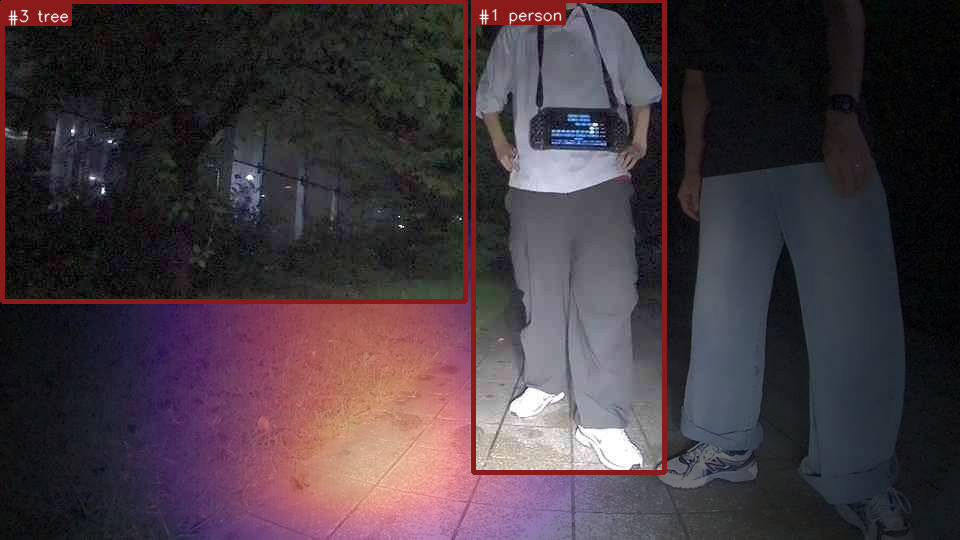
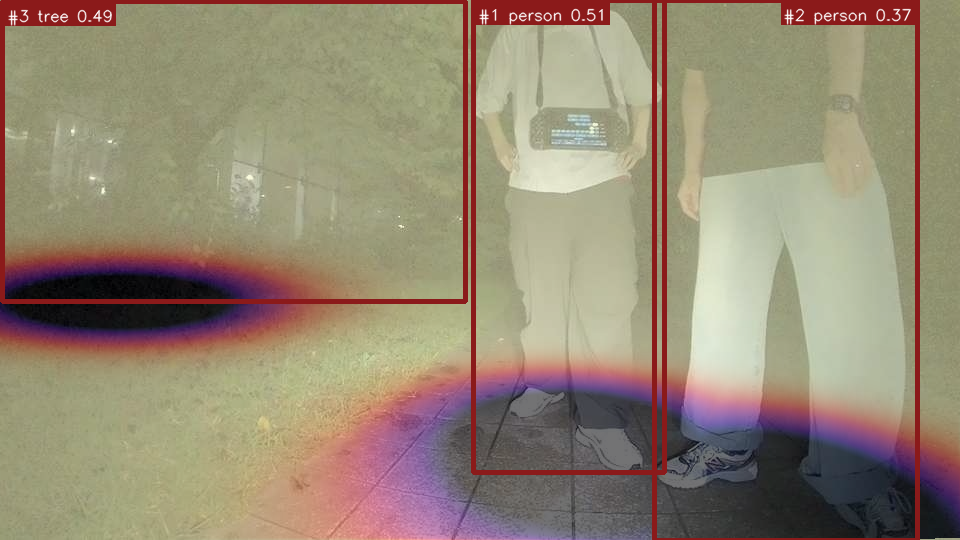
A VLM recasts the pivot frame (red) and the instruction into four judgments, which expert vision models ground into component cost maps and compose into the pivot Cost map. Each current frame (green) rebuilds only the traversability and keep-out components without a new VLM call, and the decoder's candidate trajectories are scored on both maps before the best one is executed.
Real Robot Experiment
Click an episode to watch the run.
Ablation
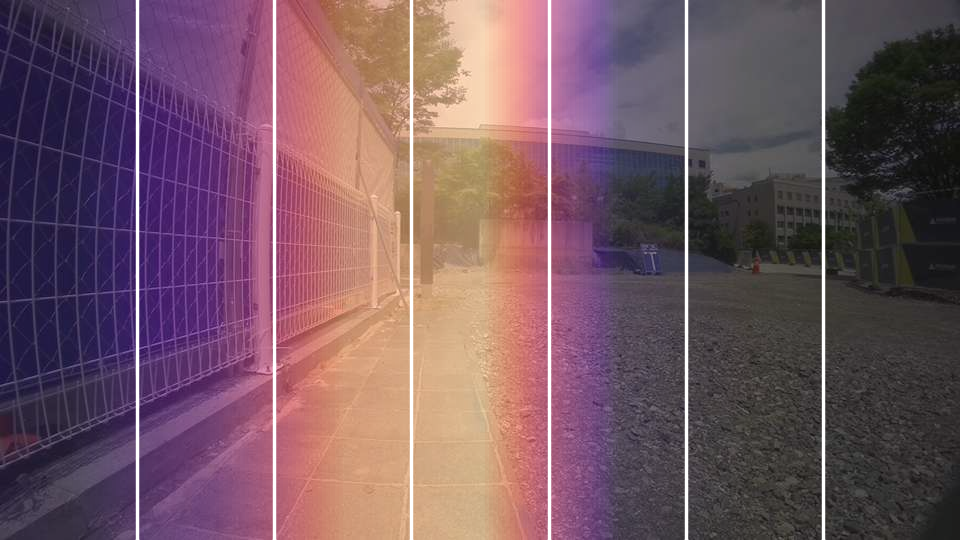
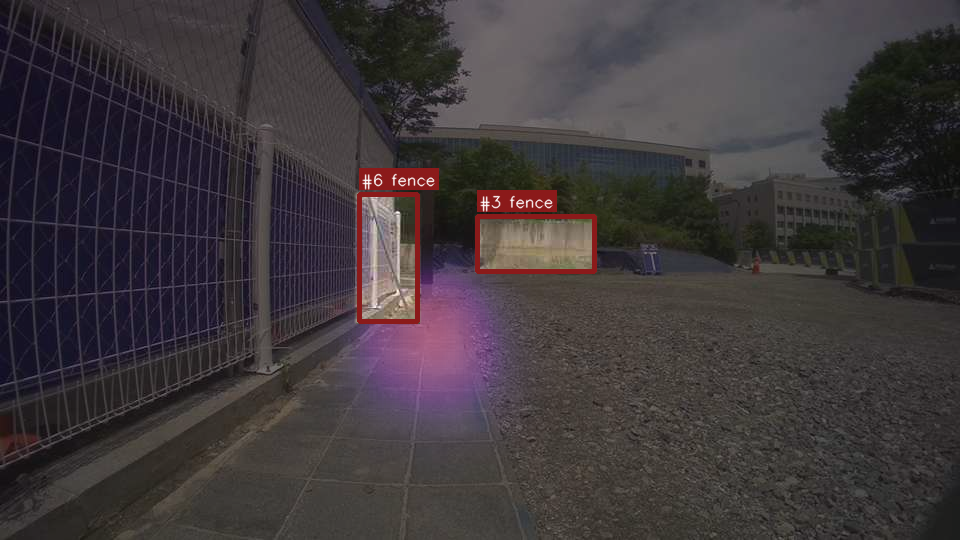
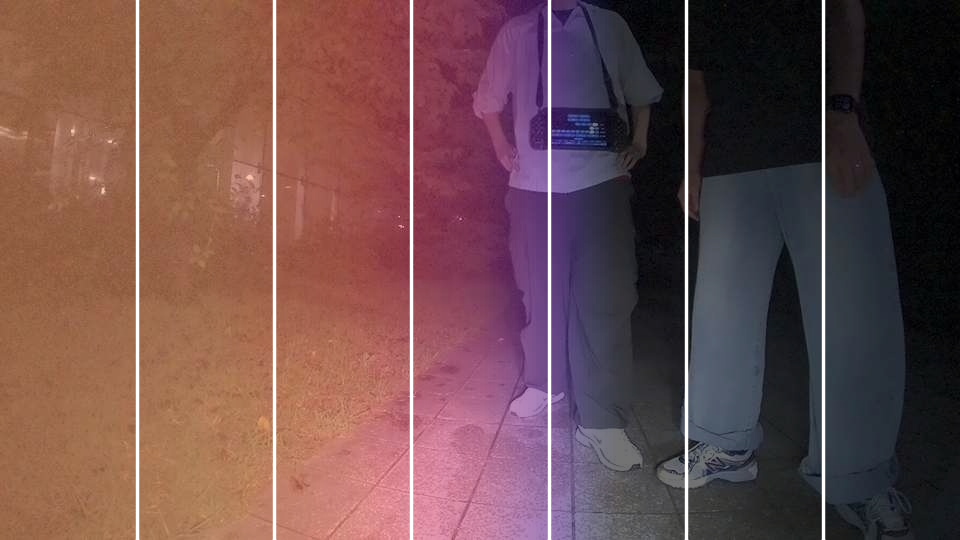
Add one sentence, and RECAST reads the same scene differently and moves differently, with no retraining.
Additional Instruction AAdditional Instruction B
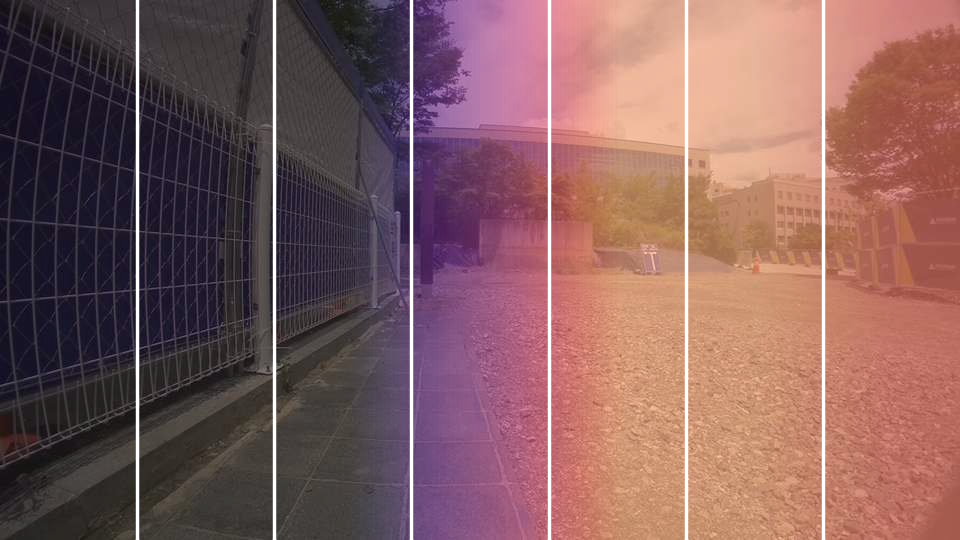
“ Stay on the paved sidewalk ”
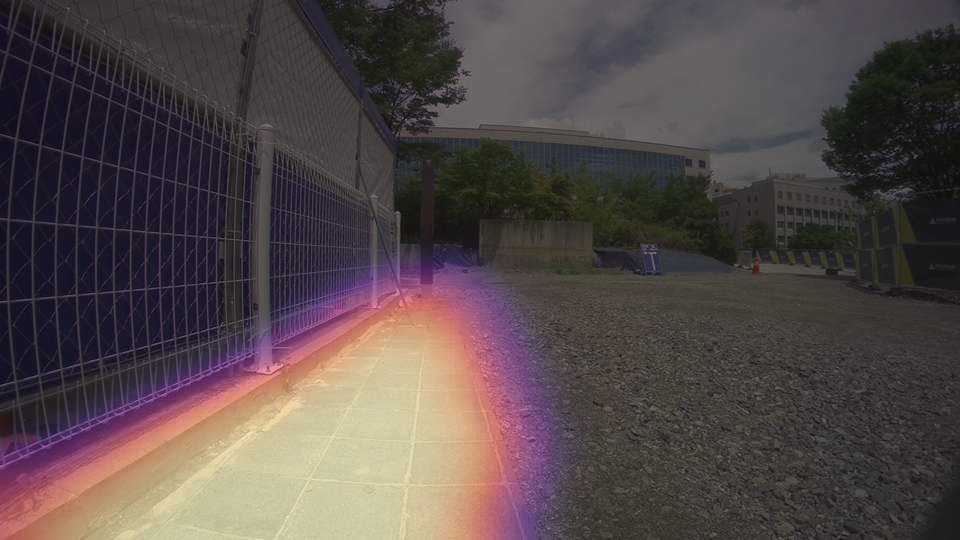
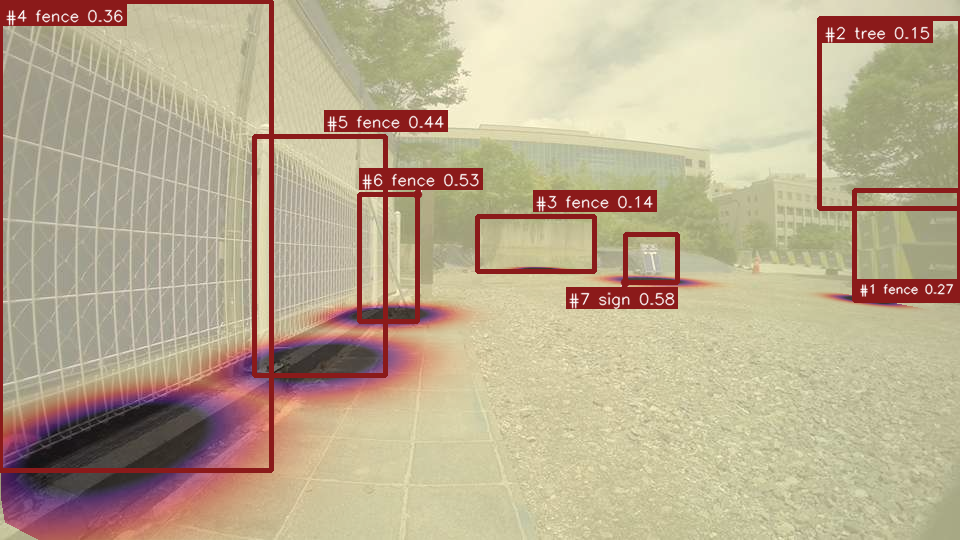
1
3
8
9
1
0
0
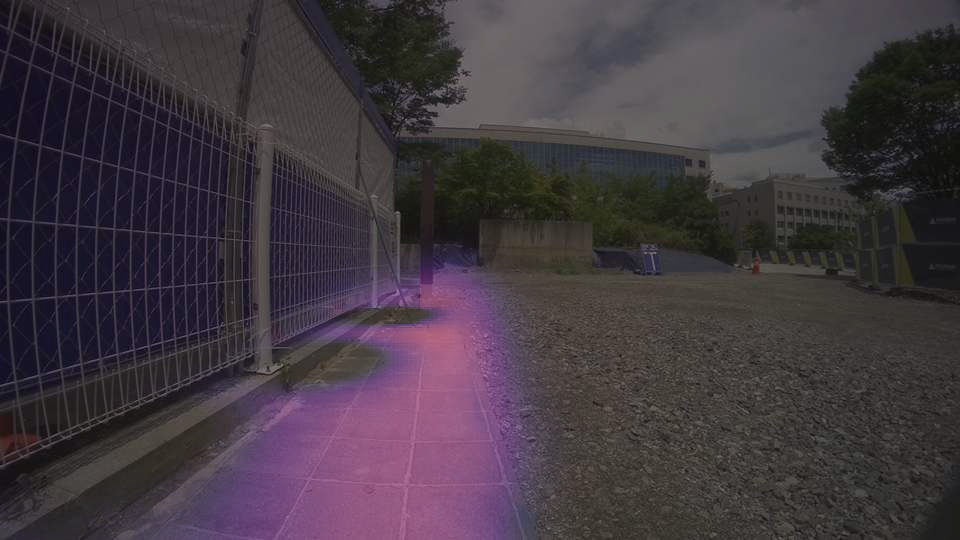

Non-Traversable
Traversable
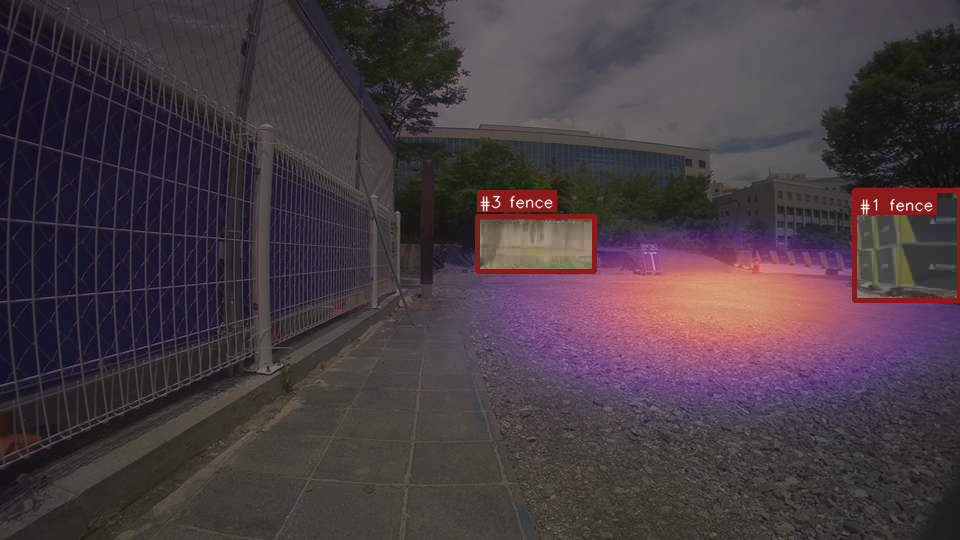
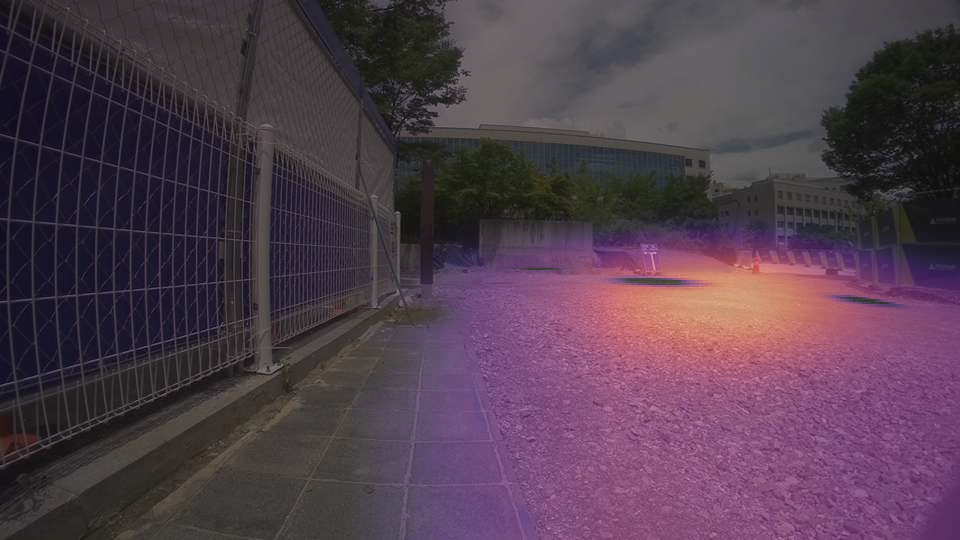
“Stay far from the construction fence, step onto gravel if needed”
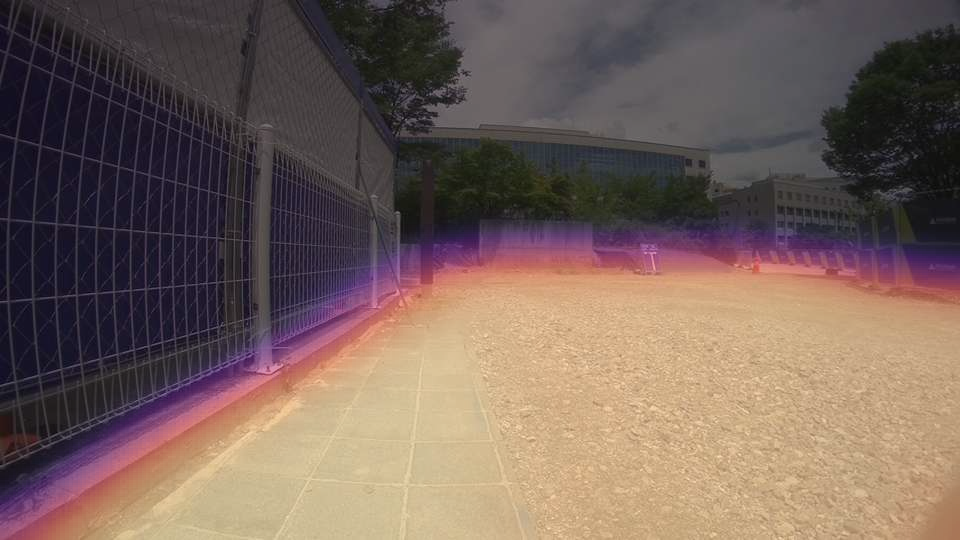
0
0
0
4
8
8
7

Non-Traversable
Traversable
“ Step onto the grass if the sidewalk is blocked ”
8
8
7
5
0
0
0
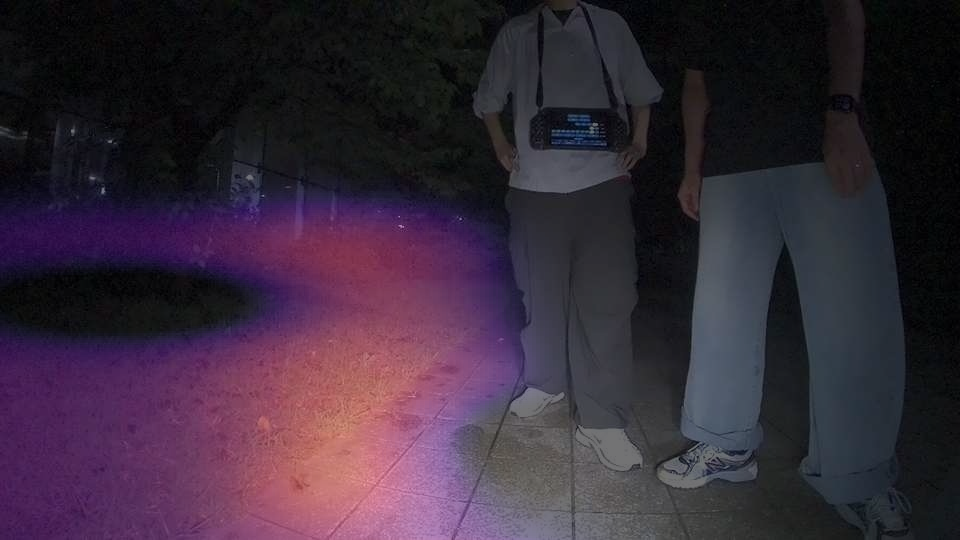

Non-Traversable
Traversable
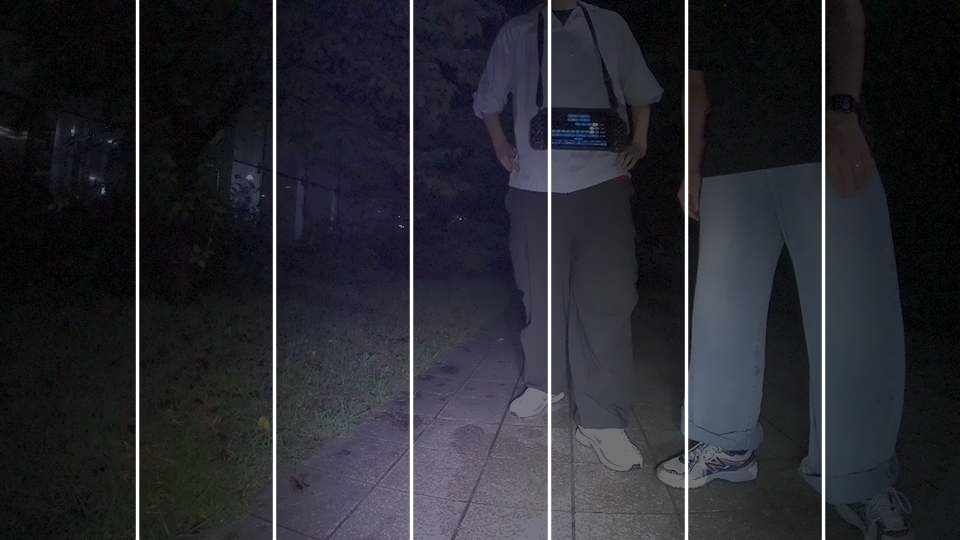
“ Never step onto the bumpy grass ”
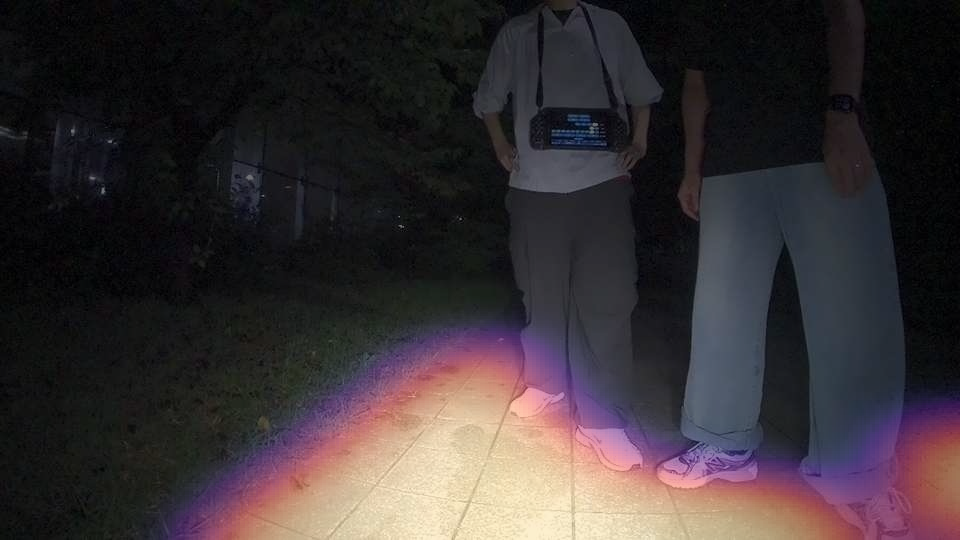
0
0
1
1
0
0
0
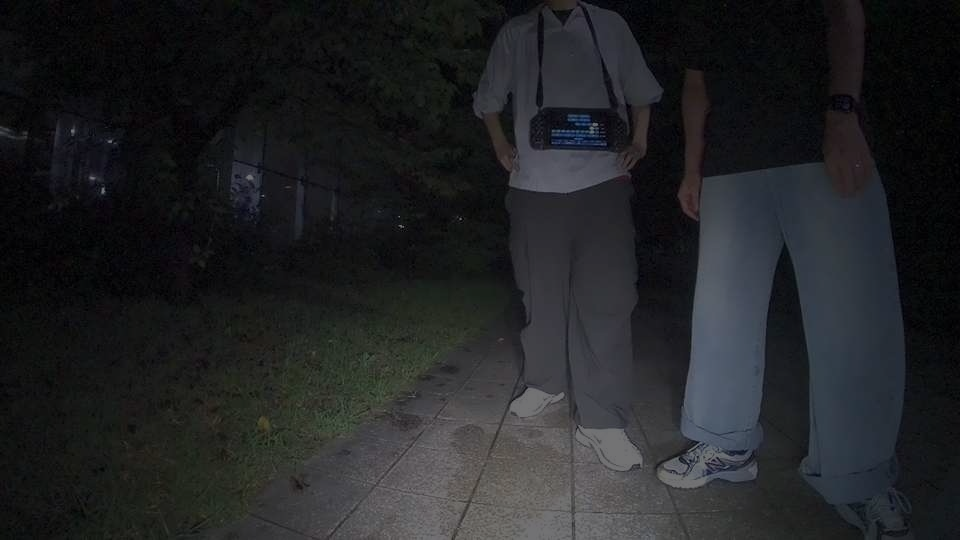
No passable gap
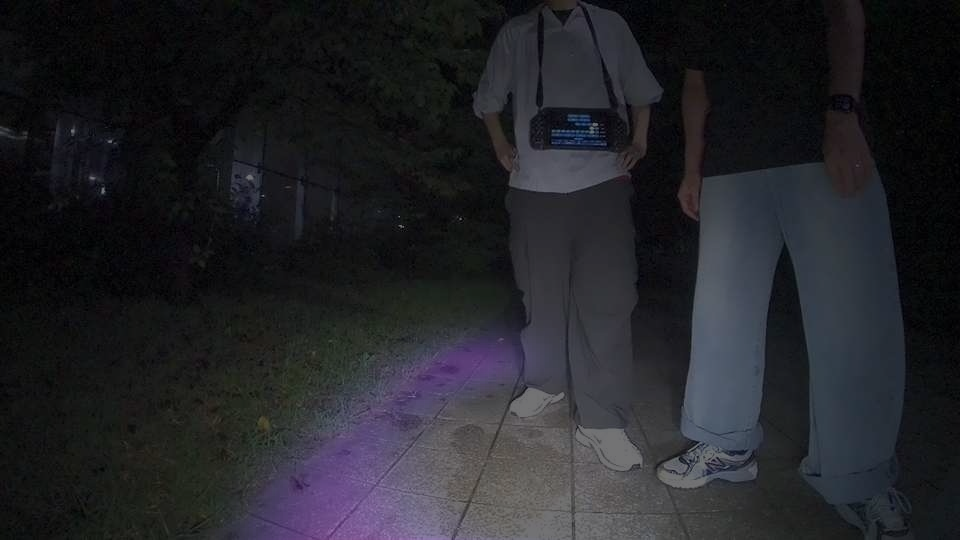

Non-Traversable
Traversable
Insufficient
actionable space
actionable space
Stop